Distinct Subsequences
Repeated characters create the trap: different selections from s can produce the same visible text in t, and the problem still counts those selections…

Distinct Subsequences
Given strings s and t, return the number of distinct subsequences of s that are equal to t. A subsequence is formed by deleting zero or more characters without changing the order of the remaining characters.
Constraints
- 1 <= s.length, t.length <= 1000
- s and t consist of English letters.
Important details
- The test cases ensure the answer fits in a 32-bit signed integer.
- Distinct ways to select positions in s count separately when they produce t.
Key topics
Repeated characters create the trap: different selections from s can produce the same visible text in t, and the problem still counts those selections separately. The reliable model is to count position choices, not generated strings.
Read the contract: what counts as distinct?
You have a source string s and a target string t. Count the ways to select characters from s, in their original order, so that the selected characters spell t.
A subsequence may skip characters, but it cannot reorder them. This is different from a substring, which must occupy one contiguous range.
The word “distinct” is also easy to misread. Consider:
s = "aab"
t = "ab"
There are two valid selections:
- Select the first
a, thenb. - Select the second
a, thenb.
Both selections produce the text "ab", but they use different positions in s, so the answer is 2.
This is not the problem of finding every unique subsequence of one string. That separate task needs to deduplicate output values. Here, the target is already given, and the count is based on distinct choices of source positions that form it.
For the canonical problem:
1 <= len(s), len(t) <= 1000sandtcontain English letters.- The answer fits in a 32-bit signed integer.
That length limit rules out generating all subsequences. The number of pick-or-skip paths can grow exponentially. We need to count equivalent prefix situations once.
Recognize the two-prefix DP shape
The recognition clues are strong:
- There are two ordered strings.
- One string must be formed from the other.
- Progress through
sand progress throughtare both relevant. - Each source character can be skipped, or used to advance the target when the characters match.
That points to a two-dimensional dynamic programming state.
Let:
dp[i][j] = number of ways to form t[:j] using s[:i]
Here, i and j are prefix lengths, not character indices. Therefore:
s[:i]contains source positions0throughi - 1.t[:j]contains target positions0throughj - 1.- The final answer is
dp[m][n], wherem = len(s)andn = len(t).
The state has a useful geometry:
- The cell above,
dp[i - 1][j], represents skipping the newest source character. - The diagonal above-left,
dp[i - 1][j - 1], represents using the newest source character to finish the target prefix. - The diagonal is available only when the two current characters match.
A brute-force recursion would make the same decisions:
- Skip
s[i - 1]. - If it matches
t[j - 1], use it.
But many branches reach the same pair of prefix lengths. Once the answer for (i, j) is known, recomputing it is wasted work. Dynamic programming stores that repeated result.
Derive the recurrence from the newest source character
Look at s[i - 1], the newest character in the current source prefix.
Mismatch
If:
s[i - 1] != t[j - 1]
then the newest source character cannot be the final character of t[:j]. It must be skipped:
dp[i][j] = dp[i - 1][j]
The source becomes one character shorter, while the target prefix stays the same.
Match
If:
s[i - 1] == t[j - 1]
every valid selection falls into exactly one of two groups:
- It skips
s[i - 1]. - It uses
s[i - 1]as the final selected character.
The first group contributes:
dp[i - 1][j]
The second group must form t[:j - 1] from s[:i - 1] before appending the matching character. It contributes:
dp[i - 1][j - 1]
Therefore:
dp[i][j] = dp[i - 1][j] + dp[i - 1][j - 1]
The addition is safe because the two groups are disjoint. A selection either includes the newest source position or it does not. It cannot belong to both groups.
The full recurrence is:
if s[i - 1] == t[j - 1]:
    dp[i][j] = dp[i - 1][j] + dp[i - 1][j - 1]
else:
    dp[i][j] = dp[i - 1][j]
Base cases
The empty target is the critical boundary:
dp[i][0] = 1
for every i.
There is exactly one way to form an empty target from any source prefix: select nothing. This is the empty selection. It acts as the seed that allows a first matching character to contribute.
For an empty source and a nonempty target:
dp[0][j] = 0 for j > 0
There are no source positions available, so no nonempty target can be formed.
Failure mode: If you initialize the empty-target column to zero, every later match loses its diagonal starting point. The table will report zero even when valid subsequences exist.
Prove that the table counts the right thing
The invariant is:
dp[i][j]equals the number of distinct selections of positions froms[:i]whose selected characters spellt[:j].
We prove this by induction over increasing source and target prefix lengths.
For the base cases:
dp[i][0] = 1because selecting no positions is the one way to produce the empty target.dp[0][j] = 0forj > 0because an empty source cannot produce a nonempty target.
Now assume the invariant holds for smaller source prefixes.
For dp[i][j], classify every valid selection according to whether it uses the newest source position, i - 1.
- If it does not use that position, the selection comes from
s[:i - 1]and contributesdp[i - 1][j]. - If it does use that position, its character must equal
t[j - 1]. The earlier selected positions must formt[:j - 1]froms[:i - 1], contributingdp[i - 1][j - 1].
If the characters do not match, the second category is impossible. If they do match, the categories are exhaustive and disjoint. By the induction hypothesis, both smaller table entries count their selections correctly, so their sum does too.
Thus the invariant holds for every cell, and dp[m][n] is the required answer.
Notice what the proof counts: source-position selections. It does not construct strings and then deduplicate them. That distinction is the core of the problem.
Dry-run with repeated characters
Use:
s = "aab"
t = "ab"
The table has one extra row and column for empty prefixes:
s[:i] \ t[:j] | "" | "a" | "ab" |
|---|---|---|---|
"" | 1 | 0 | 0 |
"a" | 1 | 1 | 0 |
"aa" | 1 | 2 | 0 |
"aab" | 1 | 2 | 2 |
Read the transitions:
- The first
amatches target"a", sodp[1][1] = 1. - The second
aalso matches. It can be skipped or used, sodp[2][1] = 1 + 1 = 2. - The final
bmatches the target’s last character. It must follow either of the two ways to form"a", sodp[3][2] = 2.
The table branches at the repeated character without storing any strings or sets. It remembers only how many valid position selections reach each prefix state.
For a debugging pass, print or write this table by hand. A mismatch should copy the value above. A match should add the value above to the diagonal. If those two physical movements are not visible in your implementation, the indexing is probably obscuring the logic.
Implement the full 2D solution in Python
The full table is my preferred first implementation in an interview. It mirrors the definition, makes the proof visible, and is easier to inspect when a boundary case fails.
class Solution:
    def numDistinct(self, s: str, t: str) -> int:
        m = len(s)
        n = len(t)

        # dp[i][j] = ways to form t[:j] from s[:i]
        dp = [[0] * (n + 1) for _ in range(m + 1)]

        # The empty target has one formation: select nothing.
        for i in range(m + 1):
            dp[i][0] = 1

        for i in range(1, m + 1):
            for j in range(1, n + 1):
                # Skip s[i - 1].
                dp[i][j] = dp[i - 1][j]

                # If it matches, also use s[i - 1] for t[j - 1].
                if s[i - 1] == t[j - 1]:
                    dp[i][j] += dp[i - 1][j - 1]

        return dp[m][n]
The loop order is deliberate:
- The outer loop adds one source character at a time.
- The inner loop evaluates all target prefixes for that source prefix.
- Every dependency comes from the previous source row, which has already been computed.
The i - 1 and j - 1 expressions are the bridge between prefix-based DP and zero-based Python strings. Keeping that mapping explicit prevents one of the most common bugs in this problem: using s[i] or t[j] while the DP indices are already one-based.
No modulo operation is needed. The problem guarantees that the final answer fits in a 32-bit signed integer.
Compress the table to O(n) space
Each row depends only on the previous row. We can remove the source dimension and retain one array indexed by target prefix length.
Define:
dp[j] = current number of ways to form t[:j]
Before processing any source characters:
dp[0] = 1
dp[j] = 0 for j > 0
When a source character matches t[j - 1], the transition is still:
dp[j] = old_dp[j] + old_dp[j - 1]
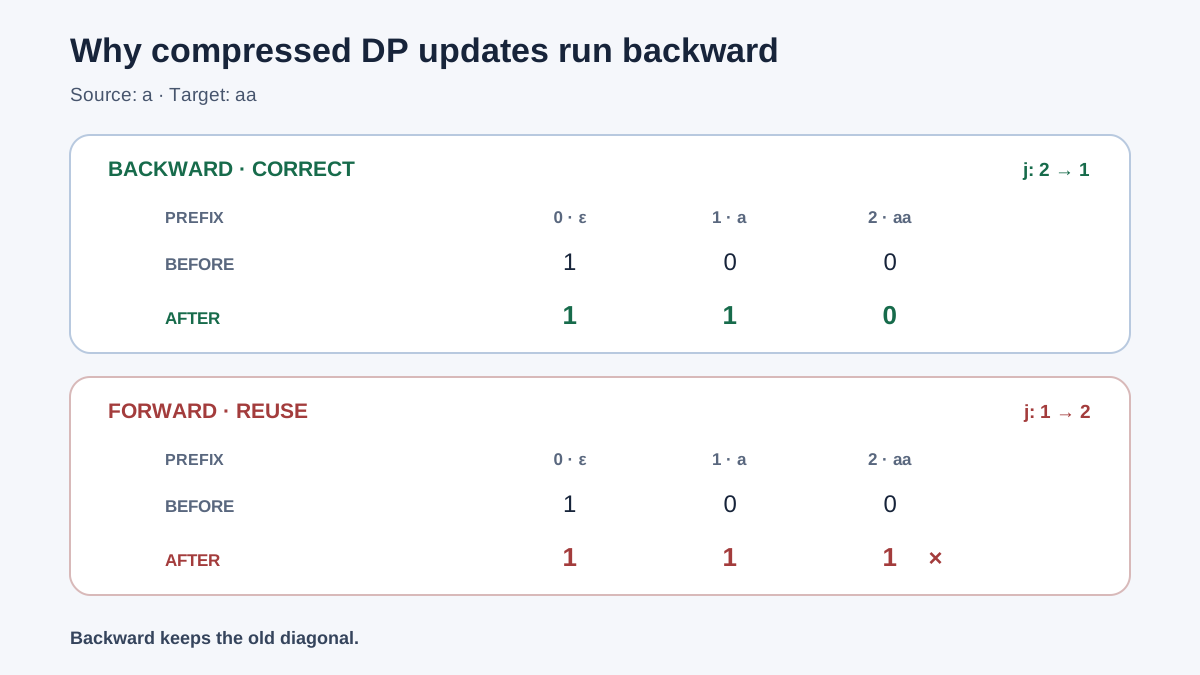
The problem is that dp[j] is updated in place. If we iterate j from left to right, dp[j - 1] may already belong to the current source row. That would incorrectly allow the same source character to advance through multiple target positions.
Iterate backward instead. Then dp[j - 1] still represents the previous source row when it is needed.
class Solution:
    def numDistinct(self, s: str, t: str) -> int:
        n = len(t)

        # dp[j] = ways to form t[:j] from the source processed so far
        dp = [0] * (n + 1)
        dp[0] = 1

        for source_char in s:
            for j in range(n, 0, -1):
                if source_char == t[j - 1]:
                    dp[j] += dp[j - 1]

        return dp[n]
This is not a memorized direction trick. It follows directly from dependency preservation:
dp[j]is the old row’sdp[i - 1][j]before an update.dp[j - 1]must remain the old row’s diagonal value.- Updating from right to left prevents the diagonal from being overwritten too early.
Compressed-state invariant: Before updating position
jfor the current source character,dp[j - 1]still describes the previous source prefix.
The compressed version is the better production shape when memory matters. The full table is the better explanation and debugging artifact. Both perform the same recurrence.
Complexity, edge cases, and interview checks
Let:
m = len(s)
n = len(t)
Complexity
For every source prefix and target prefix, the 2D algorithm performs constant work:
- Time:
O(mn) - Full-table space:
O(mn)
The compressed algorithm still examines every source-target pair:
- Time:
O(mn) - Space:
O(n)
The space depends on the target because the target dimension is retained. If the strings have very different lengths, this direction matters operationally.
Edge cases
Check these before trusting the implementation:
- Target longer than source: The answer is zero. There are not enough source positions to select.
- No matching characters: Every nonempty target state remains zero.
- All characters match: The count reflects multiple choices of source positions, not one obvious alignment.
- Repeated characters: Never use a set of generated strings. Position selections are what must be counted.
- Empty target: Conceptually, the answer is one. The empty-target column must be initialized to one, even though the stated input constraints require nonempty strings.
- Single-character target: The answer is simply the number of matching source positions. This is a useful sanity check for the recurrence.
- Compressed implementation: Iterate the target index backward. Left-to-right updates count illegal reuse of the current source character.
Two quick debugging properties are especially useful:
- For a fixed target prefix, its count cannot decrease as more source characters become available.
- A target prefix longer than the processed source prefix must have count zero.
The tempting wrong approaches are predictable:
- Generate every subsequence: exponential branching and unnecessary string allocation.
- Generate subsequences into a set: still exponential, and it solves the wrong distinction.
- Use only matching character counts: order matters, so frequency alone cannot determine the answer.
- Update the one-dimensional array left-to-right: the current source character can leak into multiple target positions.
- Forget the empty-target base case: every construction loses its starting state.
The reusable rule is simple:
When one ordered sequence must be formed from another, and progress is described by two prefix lengths, define what each paired-prefix count means before writing transitions. Then partition by the newest source position: skip it, or use it exactly once. Compress the table only after the dependency direction is clear.
References
Practice interview patterns more systematically
Use structured problem sets and pattern references to turn isolated solutions into reusable interview judgment.


