Pascal's Triangle II
The requested output is one row, not the entire triangle. Build that row with one working list, and update it from right to left so each calculation still…

Pascal's Triangle II
Given a non-negative integer rowIndex, return the row of Pascal's triangle at zero-based index rowIndex. Each entry is formed by summing the two entries directly above it, with edge entries equal to 1.
Constraints
- 0 <= rowIndex <= 33
Important details
- The row index is 0-based.
- Return only the requested row, as an ordered list of integers.
- The source includes a follow-up asking whether the row can be computed with O(rowIndex) extra space.
Key topics
The requested output is one row, not the entire triangle. Build that row with one working list, and update it from right to left so each calculation still sees the previous row's values.
Start with the contract
Given a non-negative integer rowIndex, return the row at that zero-based index.
The first rows are:
row 0: [1]
row 1: [1, 1]
row 2: [1, 2, 1]
row 3: [1, 3, 3, 1]
row 4: [1, 4, 6, 4, 1]
Each row has three properties:
- Its length is
rowIndex + 1. - Its first and last values are
1. - Every interior value is the sum of the two values directly above it.
For example, row 4 is built from row 3:
previous:  1   3   3   1
next:      1   4   6   4   1
The recurrence for an interior position j is:
current[j] = previous[j - 1] + previous[j]
The input constraint is:
0 <= rowIndex <= 33
Because the index is zero-based, rowIndex = 0 returns [1], not [1, 1].
Identify the recurrence
A direct solution could construct every row from row 0 through rowIndex and retain the entire triangle. That works, but it stores data the caller never requests.
Only the previous row is needed to construct the next one. This gives three storage choices:
- Store the entire triangle:
O(n²)space. - Store a previous row and a current row:
O(n)space. - Reuse one list for both rows:
O(n)space with less working storage.
The third option is the useful optimization, but it introduces a state-management problem. During an update, one list contains a mixture of old and new values:
- positions already processed belong to the new row;
- positions not yet processed still belong to the previous row.
The loop direction must preserve the values that future calculations have not read yet.
Derive the one-list algorithm
Allocate a list with the final answer's length:
row = [1] * (rowIndex + 1)
This gives every position its eventual boundary value. More precisely, before constructing row i, only the prefix row[0:i] represents the previous row. The rest of the list is unused storage, already filled with 1s so that the next position can become the new row's right boundary.
For example, with rowIndex = 4:
initial list: [1, 1, 1, 1, 1]
active prefix: [1]
Build the rows one at a time. For each target row i, update its interior positions from i - 1 down to 1.
The update is:
row[position] += row[position - 1]
This is equivalent to:
row[position] = row[position] + row[position - 1]
The right-to-left order matters because row[position - 1] must still contain its previous-row value.
A literal state trace
For rowIndex = 4, the allocated list has five slots. The active prefix expands after each outer-loop pass.
Before building row 2:
list:   [1, 1, 1, 1, 1]
active: [1, 1]       # row 1
Update position 1:
[1, 1 + 1, 1, 1, 1]
[1, 2,     1, 1, 1]
Now the active prefix is row 2:
[1, 2, 1]
Before building row 3, that prefix is the previous row. Process position 2 first, then position 1:
position 2: [1, 2, 2 + 1, 1, 1] -> [1, 2, 3, 1, 1]
position 1: [1, 2 + 1, 3,     1, 1] -> [1, 3, 3, 1, 1]
The active prefix is now:
[1, 3, 3, 1]
Build row 4 in the same direction:
position 3: [1, 3, 3, 3 + 1, 1] -> [1, 3, 3, 4, 1]
position 2: [1, 3, 3 + 3,     4, 1] -> [1, 3, 6, 4, 1]
position 1: [1, 3 + 1, 6,       4, 1] -> [1, 4, 6, 4, 1]
The requested row is the first five positions.
The suffix values in the initial list are not pretending to be part of the current row. They are inactive storage. The active prefix is what carries the algorithm's meaningful state.
Why right to left is required
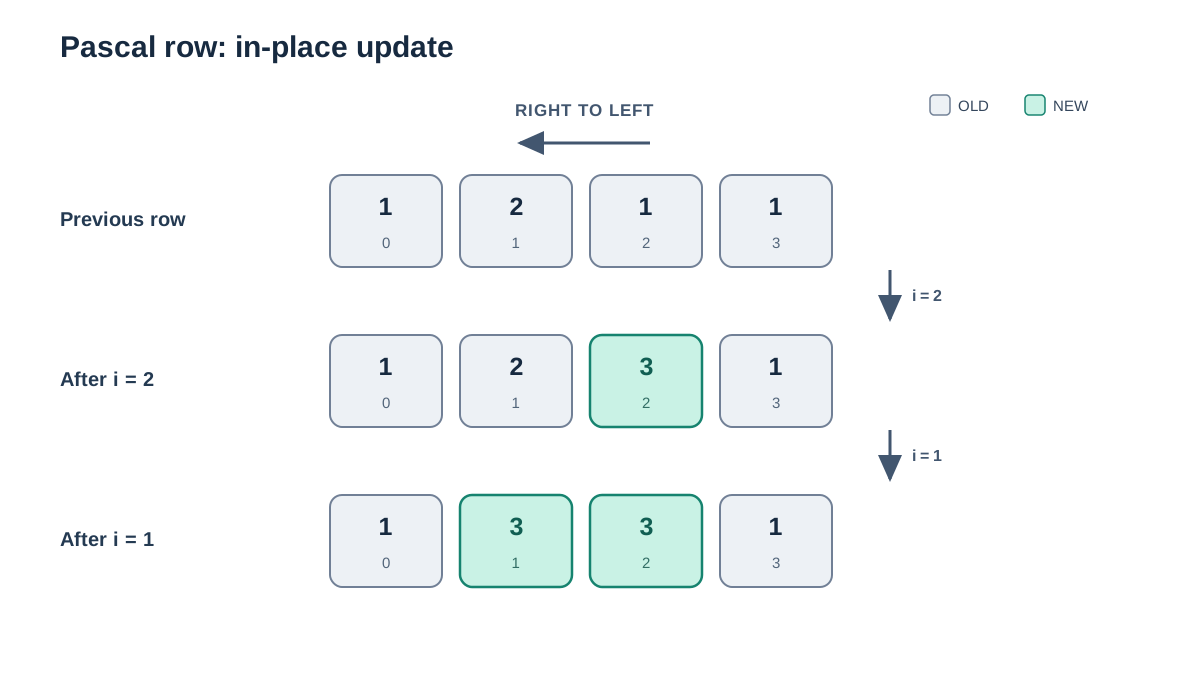
Suppose the previous row is:
[1, 2, 1, 1]
The next row should be:
[1, 3, 3, 1]
A left-to-right update starts at position 1:
row[1] = row[1] + row[0]
[1, 3, 1, 1]
Now position 2 is calculated using row[1]:
row[2] = row[2] + row[1]
[1, 3, 4, 1]
That is wrong. Position 2 needed the old value 2 from the previous row, but position 1 has already become 3.
The new value leaked into a calculation that still required old state.
With right-to-left traversal, position 2 is computed before position 1 changes:
position 2: 1 + 2 = 3
position 1: 2 + 1 = 3
In-place dynamic programming rule: choose an update direction that keeps every unread dependency in its old state.
For this recurrence, each position reads its left neighbor. Processing from right to left means that left neighbor has not been updated yet.
The invariant that proves correctness
The key invariant is:
Before building row
i, the active prefixrow[0:i]contains rowi - 1. During the update, positions greater than the current position contain new-row values, while positions at or below the current position still contain old-row values until they are processed.
Consider an interior position j while building row i.
The recurrence requires:
current[j] = previous[j] + previous[j - 1]
The code computes:
row[j] += row[j - 1]
Because positions are processed from right to left:
row[j]has not been updated yet, so it is stillprevious[j];row[j - 1]has not been updated yet, so it is stillprevious[j - 1].
Therefore, the addition uses exactly the two values required by the recurrence.
After position j is updated, it correctly stores current[j]. The algorithm then moves to j - 1, where the same argument applies.
Position 0 remains 1. Position i, the new right boundary, was initialized as 1 and is not included in the inner loop. Therefore, after all interior positions are processed, the active prefix row[0:i + 1] is exactly row i.
For the base cases:
rowIndex = 0starts with[1];rowIndex = 1starts with[1, 1].
Those rows require no interior updates. Repeating the invariant-preserving update through the requested index produces the correct result.
The trace shows what happens. The invariant explains why it must happen correctly.
Python implementation
class Solution:
    def getRow(self, rowIndex: int) -> list[int]:
        row = [1] * (rowIndex + 1)

        for current_row in range(2, rowIndex + 1):
            for position in range(current_row - 1, 0, -1):
                row[position] += row[position - 1]

        return row
The outer loop constructs rows 2 through rowIndex. Rows 0 and 1 are already represented by the initial list.
For each current_row, the inner loop visits:
current_row - 1, current_row - 2, ..., 1
It skips both boundaries and moves backward so that every unread dependency remains part of the previous row.
For rowIndex = 3, the state is:
initial:       [1, 1, 1, 1]

current_row=2
position=1:    [1, 2, 1, 1]

current_row=3
position=2:    [1, 2, 3, 1]
position=1:    [1, 3, 3, 1]
The returned value is:
[1, 3, 3, 1]
The list is both the working state and the final output. No complete triangle and no second row are required.
Complexity
Let n = rowIndex.
Building row 2 performs one interior update. Building row 3 performs two. Building row n performs n - 1.
The total number of updates is:
1 + 2 + ... + (n - 1)
So the time complexity is:
O(n²)
The list contains n + 1 values, giving:
O(n)
space complexity.
The algorithm uses O(1) auxiliary space beyond the returned list because the output list is also the working list.
Edge cases and common mistakes
rowIndex = 0
Initialization produces:
[1]
Both loops skip, and the correct row is returned.
rowIndex = 1
Initialization produces:
[1, 1]
Again, no interior update is needed.
rowIndex = 2
The only interior position is 1:
[1, 1, 1] -> [1, 2, 1]
Confusing an index with a row count
The input is a zero-based index:
- index
0has length1; - index
1has length2; - index
3has length4.
The result always contains:
rowIndex + 1
values.
Updating a boundary
The inner loop must stop before position 0:
range(current_row - 1, 0, -1)
Position 0 stays 1, and position current_row remains the new row's right boundary. Updating either boundary breaks the row structure.
Updating left to right
A forward loop overwrites a dependency before it has been used. If an in-place dynamic-programming solution produces an unexpected value, inspect the update order first. The bug may be state contamination rather than an incorrect recurrence.
The transferable interview pattern
When a problem builds one layer from the previous layer, first name the dependencies. Then decide whether the old layer can be overwritten safely.
For Pascal's Triangle II:
- The whole triangle is unnecessary.
- Only the previous row is needed.
- One list can represent both rows.
- Right-to-left traversal preserves unread old values.
- The boundaries remain
1.
The durable rule is:
Compress state only after naming its dependencies. Then choose the loop direction that keeps those dependencies untouched.
That reasoning applies beyond Pascal's triangle. Whenever an in-place dynamic-programming update reads neighboring values, ask which values must remain old and which direction protects them. Do not memorize the backward loop in isolation. Trace one update, identify the value that cannot be overwritten yet, and let that obligation determine the implementation.
References
Practice interview patterns more systematically
Use structured problem sets and pattern references to turn isolated solutions into reusable interview judgment.


